The promise of cloud computing has always been about flexibility and cost-effectiveness. Yet many organizations find themselves trapped in a cycle of unpredictable costs and underutilized or overutilized resources. EKS autoscaling, when configured well, is one of the most direct levers teams have for solving this problem.
Amazon’s Elastic Kubernetes Service (EKS) gives teams the flexibility of Kubernetes backed by the reliability and scalability of AWS. But flexibility without a scaling strategy often means paying for capacity you don’t use. Industry estimates suggest most EKS bills run 30–50% higher than necessary, with waste driven primarily by overprovisioning and inefficient autoscaling rather than Kubernetes itself being expensive.
This article walks through the primary EKS autoscaling strategies—Horizontal Pod Autoscaling, Vertical Pod Autoscaling, Cluster Autoscaling, and Karpenter—showing how each one works, where it falls short, and how to pair scaling decisions with cost visibility for a more efficient cluster.
Introduction Into Scaling And EKS
EKS is a managed service that allows users to run Kubernetes on Amazon Web Services (AWS) without the need to install, operate, and maintain their own Kubernetes control plane or nodes. It’s designed to provide flexibility of Kubernetes with reliability, security, and scalability of AWS.
One of the standout features of EKS is its ability to auto-scale, ensuring optimal resource utilization and cost management. There are four primary autoscaling strategies and tools within EKS:
- Horizontal Pod Autoscaling (HPA)
- Vertical Pod Autoscaling (VPA)
- Cluster Autoscaling
- Karpenter (node-level autoscaling)
Let’s spend some time going over each of these options.
Report
Finance needs to prove AI’s return: CloudZero report
260 senior finance leaders (more than half CFOs) told us why the speed of seeing AI spend, not the size of it, separates who pulls ahead on AI from who gets burned.
Horizontal Pod Autoscaling
Horizontal Pod Autoscaling is a feature within Kubernetes that automatically adjusts the number of pod replicas in a deployment or replica set. It operates based on observed metrics such as CPU utilization, memory consumption, or custom metrics defined by the user.
When the observed metric crosses a user-defined threshold, HPA will either increase or decrease the number of pod replicas to ensure that the application can handle the current load.
The primary purpose of HPA is to ensure that applications can efficiently handle varying amounts of traffic.
For instance, during peak times, HPA can automatically scale out (increase replicas) to accommodate the increased demand. Conversely, during periods of low traffic, it can scale in (decrease replicas) to conserve resources.
This dynamic adjustment ensure that resources are not wasted on over-provisioned pods, leading to cost savings and optimized performance.
How Can We Begin Using HPA On An EKS Cluster?
Prerequisites
- Kubectl is installed and connected to your EKS cluster
- You have Metrics Server installed
- You’ve deployed an application within your cluster
Since HPA is a standard API that is part of any Kubernetes cluster deployment, leveraging HPA is as simple as running the following command to create an HPA resource:
kubectl autoscale deployment <DeploymentName> --cpu-percent=50 --min=1 --max=10
The above command will scale the specified deployment when CPU utilization crosses the 50% threshold, and will operate within a range of 1-10 replicas at any given time.
Vertical Pod Autoscaling
Vertical Pod Autoscaling automatically adjusts the CPU and memory resource requests and limits of individual pods in a Kubernetes deployment.
Unlike Horizontal Pod Autoscaling (HPA) which scales the number of pod replicas, VPA focuses on scaling the resources of existing pods. It operates by continually analyzing the consumption of resources and based on this analysis, reallocates them to ensure that pods have the resources they need without over-provisioning.
The primary purpose of VPA is to optimize resource utilization for individual pods. By dynamically adjusting resource requests and limits, VPA ensures that:
- Pods receive the necessary resources to function optimally.
- Resources are not wasted on over-allocated pods, leading to cost savings.
- The risk of pod evictions due to resource constraints is minimized.
How Can We Begin Using VPA On An EKS Cluster?
Prerequisites
- Kubectl is installed and connected to your EKS cluster
- You have Metrics Server installed
- You’ve deployed an application within your cluster
The process of using VPA is a little more complicated than with HPA, and requires the installation of the tool through the command line.
1. Clone the kubernetes/autoscaler GitHub repository
git clone https://github.com/kubernetes/autoscaler.git
2. Change to the vertical-pod-autoscaler directory
cd autoscaler/vertical-pod-autoscaler/
3. Deploy the Vertical Pod Autoscaler to your cluster with the following command
./hack/vpa-up.sh
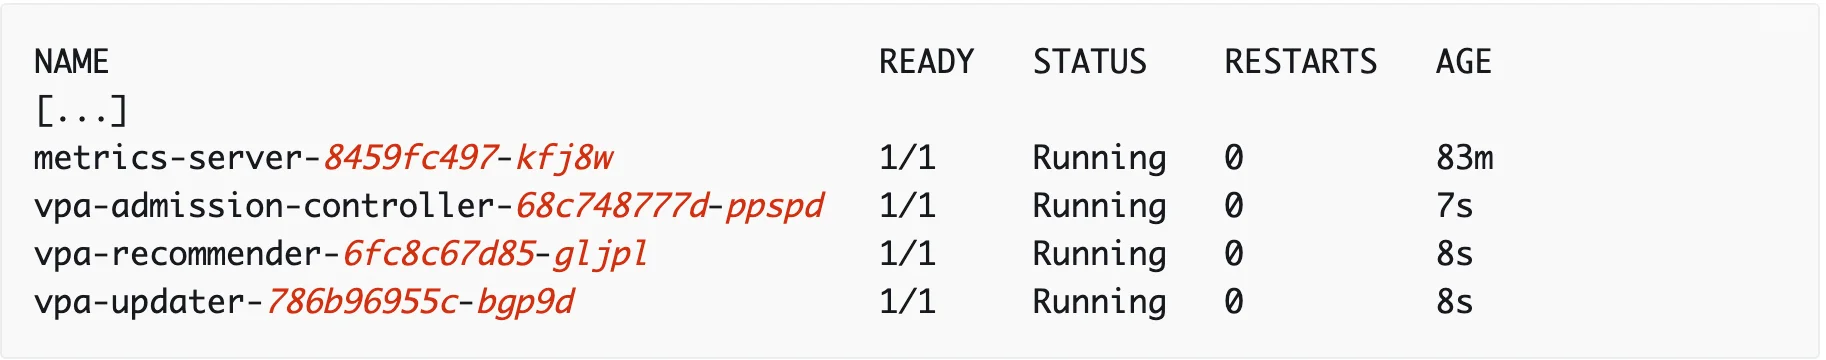
4. Verify that the Vertical Pod Autoscaler Pods have been created successfully
kubectl get pods -n kube-system
Cluster Autoscaling
Cluster Autoscaling is a feature that adjusts the size of the cluster, meaning it adds or removes nodes based on resource requirements and constraints. If there are pods that fail to run in the cluster due to insufficient resources, CA will add more nodes.
Conversely, if nodes are underutilized and their pods can be placed elsewhere, CA will consider removing these nodes.
The primary purpose of Cluster Autoscaling are:
- Resource Optimization – Ensure that the cluster has enough resources to meet the demands of the workloads without over-provisioning, which can lead to unnecessary costs.
- Improved Availability – By automatically adding nodes when required, CA ensures that applications have the resources they need to run, leading to better availability and performance.
- Cost Efficiency – By removing underutilized nodes, CA helps in reducing costs associated with idle or underused resources.
How Can We Begin Using CA On An EKS Cluster?
Out of the traditional scaling options, CA is the most complicated to begin using. You’ll need a combination of IAM roles and policies, Service Accounts, and ConfigMaps deployed within the cluster.
Refer to the AWS EKS best practices documentation for step-by-step directions to install CA within your cluster.
Karpenter: The Modern Alternative to Cluster Autoscaler
Karpenter is an open-source node autoscaler originally developed by AWS and now part of the CNCF. Where Cluster Autoscaler works by scaling predefined Auto Scaling Groups, Karpenter takes a fundamentally different approach: it analyzes pending pod requirements in real time and provisions right-sized EC2 instances that match the actual workload. This just-in-time model eliminates much of the over-provisioning that makes traditional CA setups expensive.
The performance difference is meaningful. Karpenter typically brings new nodes online in 45–60 seconds by calling cloud APIs directly, while Cluster Autoscaler relies on Auto Scaling Group capacity changes and usually takes 3–4 minutes. For bursty or unpredictable workloads, that gap translates directly into either degraded user experience or pre-provisioned capacity sitting idle.
Karpenter also handles Spot Instances natively. You declare Spot as an accepted capacity type in your NodePool configuration, and Karpenter prioritizes cheaper Spot capacity while falling back to On-Demand when Spot is unavailable. Organizations using Karpenter with Spot and bin-packing strategies have reported around 30% savings on EC2 costs.
EKS Auto Mode
AWS introduced EKS Auto Mode in late 2024, and it changes the operational picture substantially. Auto Mode runs Karpenter as a fully managed component inside the EKS service, so teams get Karpenter’s provisioning speed and bin-packing without managing the controller themselves. With a single API call, Auto Mode provides managed compute autoscaling, application load balancing, EBS CSI, GPU support, and core networking—all pre-configured. For most AWS-native teams in 2026, EKS Auto Mode is the simplest path to efficient autoscaling.
Limitations Within Scaling Options
HPA limits
The ability to dynamically adjust the number of pod replicas based on utilization is incredibly powerful, but its reactive nature means it scales based on current conditions rather than predicting future needs.
This can lead to a slight delay in scaling during sudden traffic spikes, potentially causing service degradation.
Additionally, HPA relies on resource requests and limits set on pods. If these are not set appropriately, HPA might not function as expected, leading to over-provisioning and increased costs.
Continuously monitoring metrics and making scaling decisions can also introduce overhead, especially in large clusters, impacting cost efficiency.
VPA limits
A rather significant limitation of VPA is that when memory and CPU limits and requests are adjusted, the pod needs to be restarted, leading to brief service disruptions. This can be even more problematic for stateful workloads, like databases, which require persistent connections.
Additionally, VPA makes decisions based on historical usage, which might not always align with future demands. This reactive approach can sometimes result in over-allocation of resources, leading to unnecessary costs.
Combining VPA and HPA can also lead to conflicts, as both try to scale resources based on different criteria, complicating cost optimizations strategies.
CA limits
While CA focuses on ensuring that workloads have the necessary resources, it can sometimes lead to suboptimal scaling decisions. For instance, adding an entire node to host a small pod can be overkill, leading to underutilized resources and increased costs.
There’s also a delay between when resources are needed and when CA adds nodes, which can impact performance and user experience.
Additionally, frequent scaling actions can lead to unpredictable costs, especially if nodes are added and removed often. In scenarios with multiple node groups of varying instance types and sizes, CAs scaling decisions can become more complex, potentially impacting cost optimization.
Karpenter Considerations
Karpenter addresses many of Cluster Autoscaler’s structural limitations—particularly provisioning speed and right-sizing—but it isn’t without tradeoffs. Its proactive consolidation can cause pod disruptions if Pod Disruption Budgets aren’t configured carefully. Karpenter is also AWS-first; teams running multi-cloud Kubernetes may still prefer Cluster Autoscaler for consistency across providers.
The Pod Request Problem
One limitation cuts across all autoscaling tools: they only work as well as the pod resource requests they’re given. If a pod requests 4 vCPUs as a safety buffer but uses 1 vCPU in practice, every autoscaler—HPA, CA, or Karpenter—will provision capacity based on the inflated request. Continuous pod rightsizing is a prerequisite for getting real cost efficiency from any scaling strategy.
How CloudZero Can Help Mitigate These Issues
CloudZero is a cloud cost intelligence platform that provides real-time visibility into what’s driving your cloud spend, making it a valuable complement to EKS autoscaling. While HPA, VPA, CA, and Karpenter handle dynamic resource adjustments, they can lead to unpredictable costs and suboptimal resource allocations without visibility into the financial impact of those decisions.
CloudZero addresses this by correlating cost data with scaling events. Its Explorer feature lets teams drill into Kubernetes costs by cluster, namespace, deployment, or even individual pod—so you can see exactly which workloads are driving spend and whether your autoscaling configuration is producing the efficiency you expect. The platform also provides anomaly detection that flags unexpected cost spikes from scaling events before they compound into budget-breaking surprises.
For organizations using EKS, CloudZero’s Kubernetes integration maps container-level costs to the business dimensions that matter: teams, products, features, or customers. This turns autoscaling from a purely technical exercise into a cost optimization strategy with measurable ROI.
Conclusion
Amazon’s Elastic Kubernetes Service offers a robust suite of scaling options, from pod-level adjustments (HPA, VPA) to node-level autoscaling (Cluster Autoscaler, Karpenter) and the fully managed EKS Auto Mode. Each one addresses a different layer of the scaling problem, and the most effective EKS cost strategies combine multiple approaches.
The common thread is that scaling decisions and cost visibility should not be separate workflows. Tools like CloudZero bridge the gap between dynamic resource adjustments and cost predictability, giving teams the insights they need to harness the full potential of EKS autoscaling while keeping spend aligned with business value.